
AI Factory
Building an AI Factory for Your Studio? Start With QA
Nodemori builds AI workers for game studios. BugHunter is worker number one: it tests real builds on real devices and returns gameplay evidence.
Every run leaves two things behind: evidence your team can check, and game knowledge the next workers will read.
Your team assigns the work and stays in charge.
Define
Agree the player journey
Build
Make the scoped change
Check
Observe real gameplay
Decide
Accept or return for a fix
Failed checks return to development. The team owns the release decision.
Why QA goes first
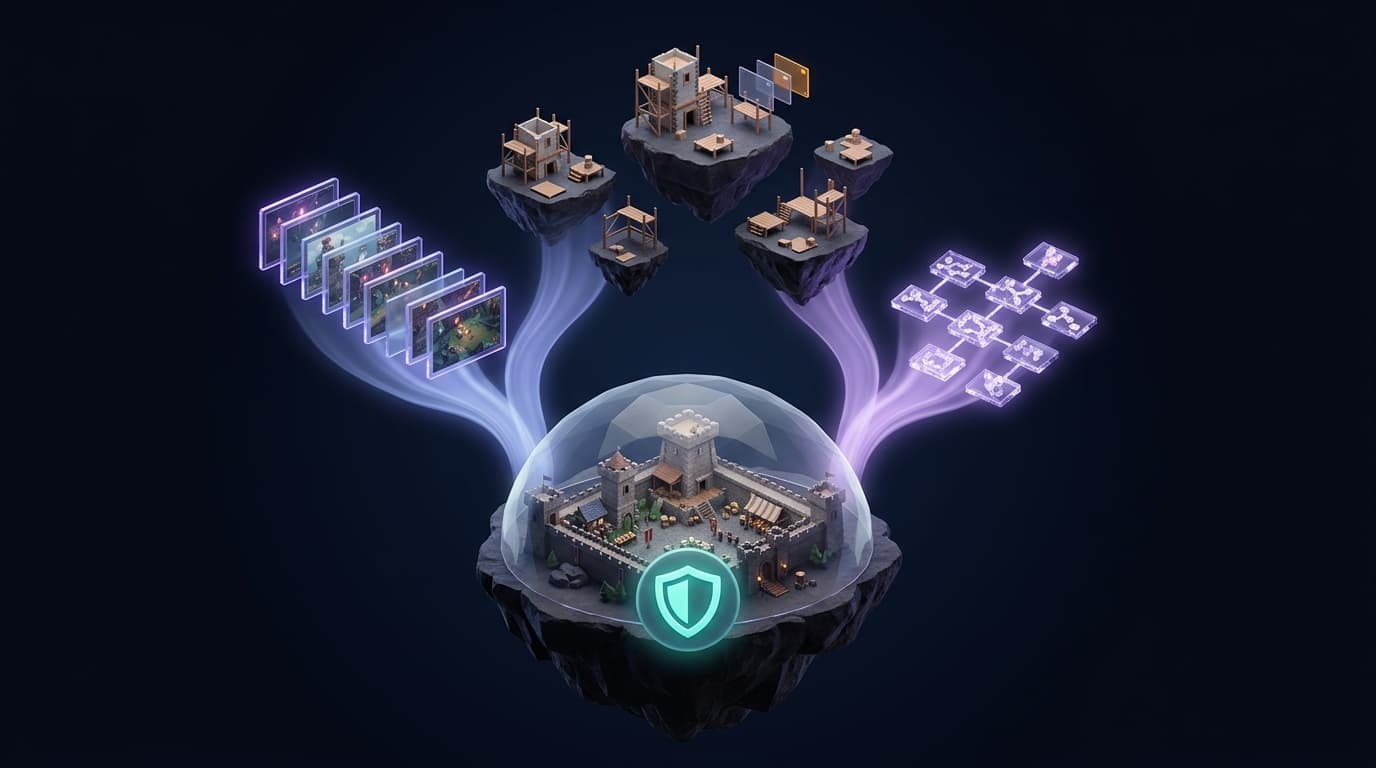
Every AI worker that comes after QA needs two things: a check nobody can fake, and knowledge about the game to build on. QA is the only job that produces both.
The evidence answers one question: did this build do what you expected? The knowledge is everything your team has learned along the way — the game's screens, mechanics, starting states, and which checks you've already accepted. Together they give the next piece of work something to aim for and something to start from.
What makes it a factory?
An AI Factory is an operating model for shipping software again and again: work enters a queue, changes happen within limits you set, checks evaluate the result, and anything that fails goes back for another attempt. You keep the goals, the boundaries, and the release call.
3ALICA's AI Factory method adds one condition that makes this work: the checks have to be cheap enough to repeat, fast enough to run often, and impossible to pass by faking the evidence instead of fixing the actual result. For a game, that means asking: what would actually convince you this player journey works on this build?
Check the complete player journey
Imagine a coding agent updating a game's reward flow. The project compiles. The unit tests pass. On a device, the player completes the level, taps Claim, and receives nothing. Faster code generation has shortened one part of delivery. The studio still needs to know whether the game works.
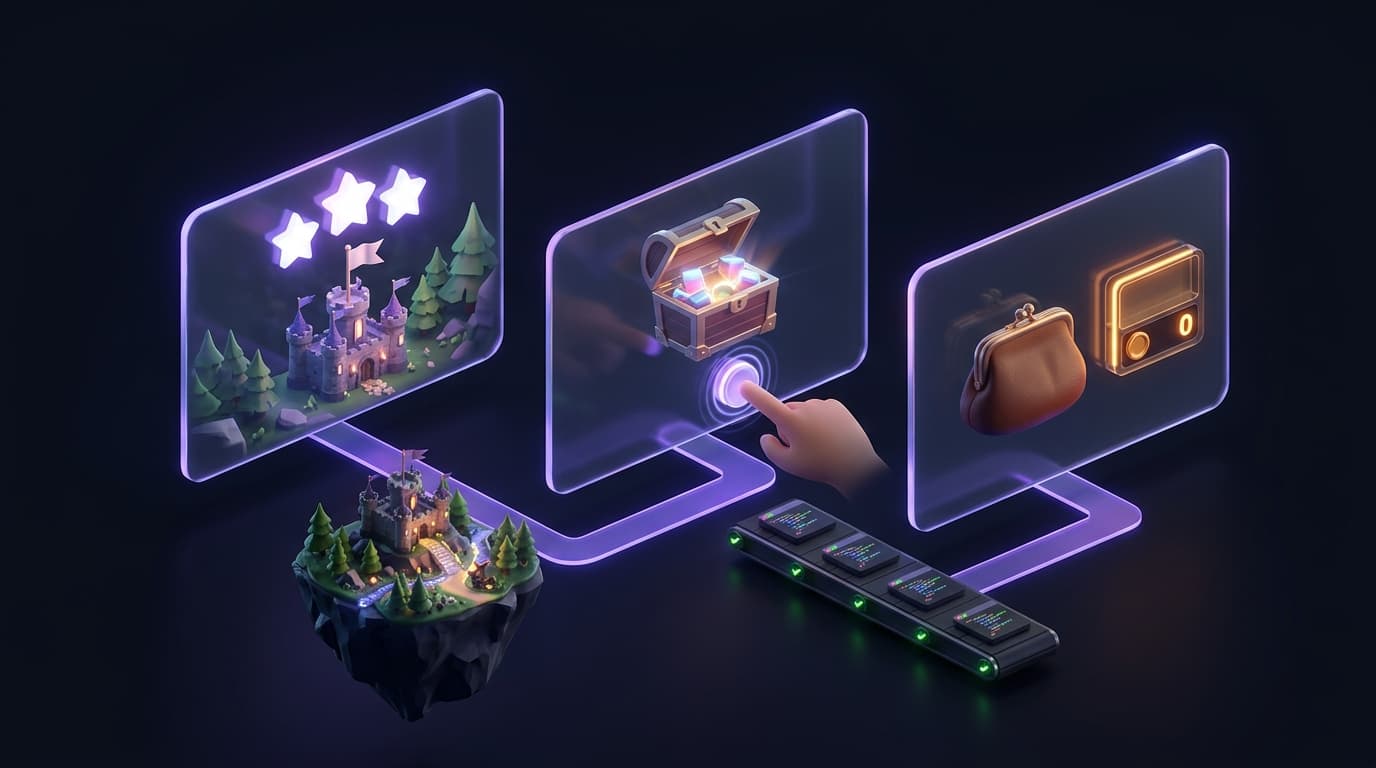
Return to the missing reward. Three checks look at it from different distances:
- A function-level test confirms that the reward calculation returns the right value. It never sees the reward screen.
- A gameplay check follows the journey: finish the level, open the reward screen, tap Claim, and inspect the balance the player sees.
- A persistence check restarts the game and confirms that the new balance is still there.
Each of these checks answers a different question. The build pipeline tells you the software compiles. Gameplay QA tells you whether one specific interaction reached the outcome you expected. Neither one, by itself, proves every player journey works.
The expectation must be agreed before the run. "The game looks fine" is too broad. "Claiming the level reward adds the specified amount once, and that balance survives a restart" gives the team a behavior it can inspect and repeat.
Write that expectation the way a tester reads it: the starting state, the steps, and the result a person can see on the screen. BugHunter takes checks in plain English, so the person who owns the feature can read and approve the exact wording before anything runs.
Turn a failed check into the next piece of work
A QA result is only useful once someone can act on it. "Reward broken" just hands the developer the job of reconstructing the build, the state, and what happened. A useful handoff ties the observation to the exact build and lays out the steps, what you expected, what actually happened, and the evidence.
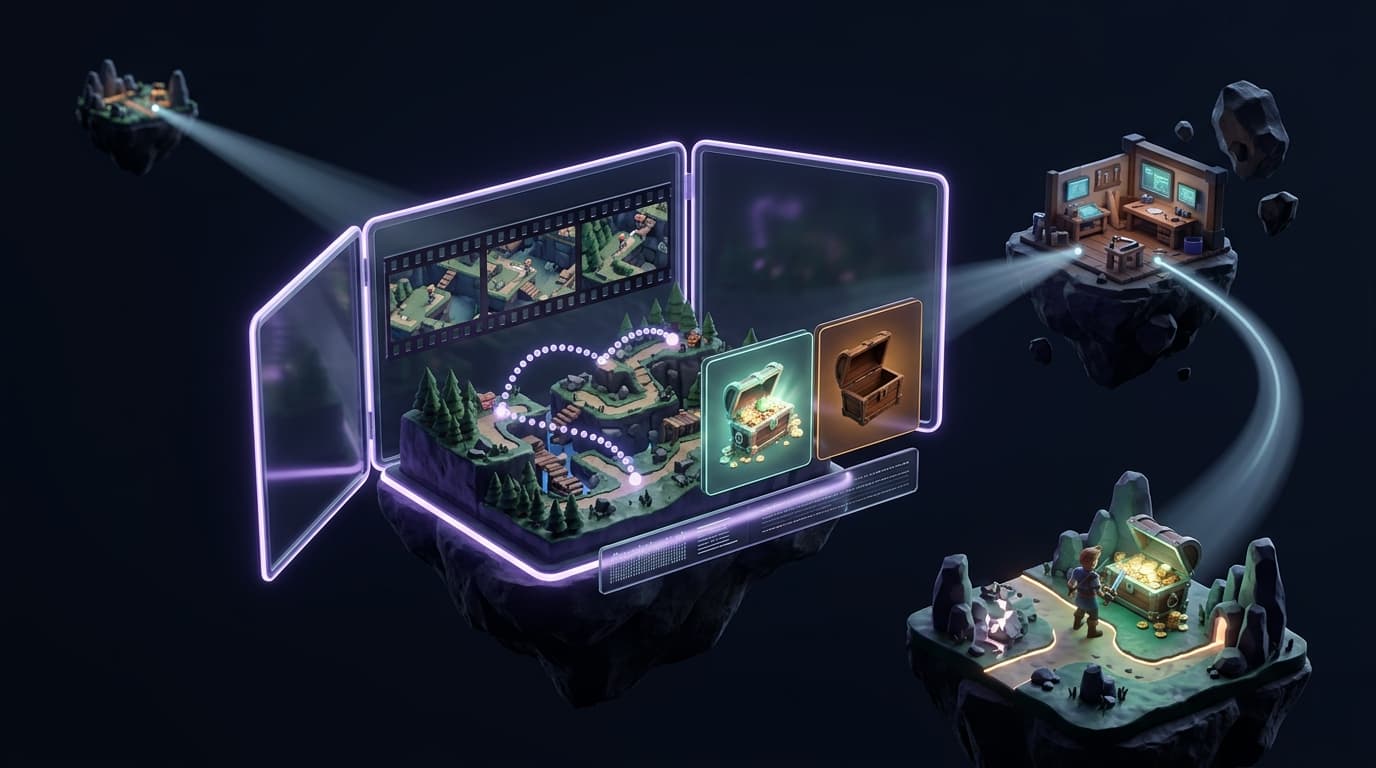
In BugHunter, a finding arrives with:
- The build and the starting state the check ran from.
- The task and its expected result, next to the behavior actually observed.
- A gameplay video and the recorded action path, so a reviewer can follow every tap.
- Logs or internal game state, where your game has them connected.
After a fix, run the same accepted check on the new build, and keep the original failure linked to the retest. That comparison — not a generated patch, not a completed run — is what tells you the fix actually worked.
And a reliable workflow doesn't paper over uncertainty. If the game never launched, the reward wasn't tested. If the run stopped early, the result is incomplete. Those need their own status — not a silent pass, and not a silent drop from the report.
BugHunter gives every check one of four results: pass, fail, blocked, or not run. If a check needs evidence BugHunter cannot observe, it reports that limit instead of counting a pass. Each finding stays pending until your QA team accepts, rejects, or merges it, and an accepted finding goes to Jira or your tracker as the next piece of work.
Game knowledge carries forward
Every QA run also teaches you something about the game — where a flow starts, what the player can do, what should happen next. Once your team accepts a finding, it becomes knowledge the next run can reuse.
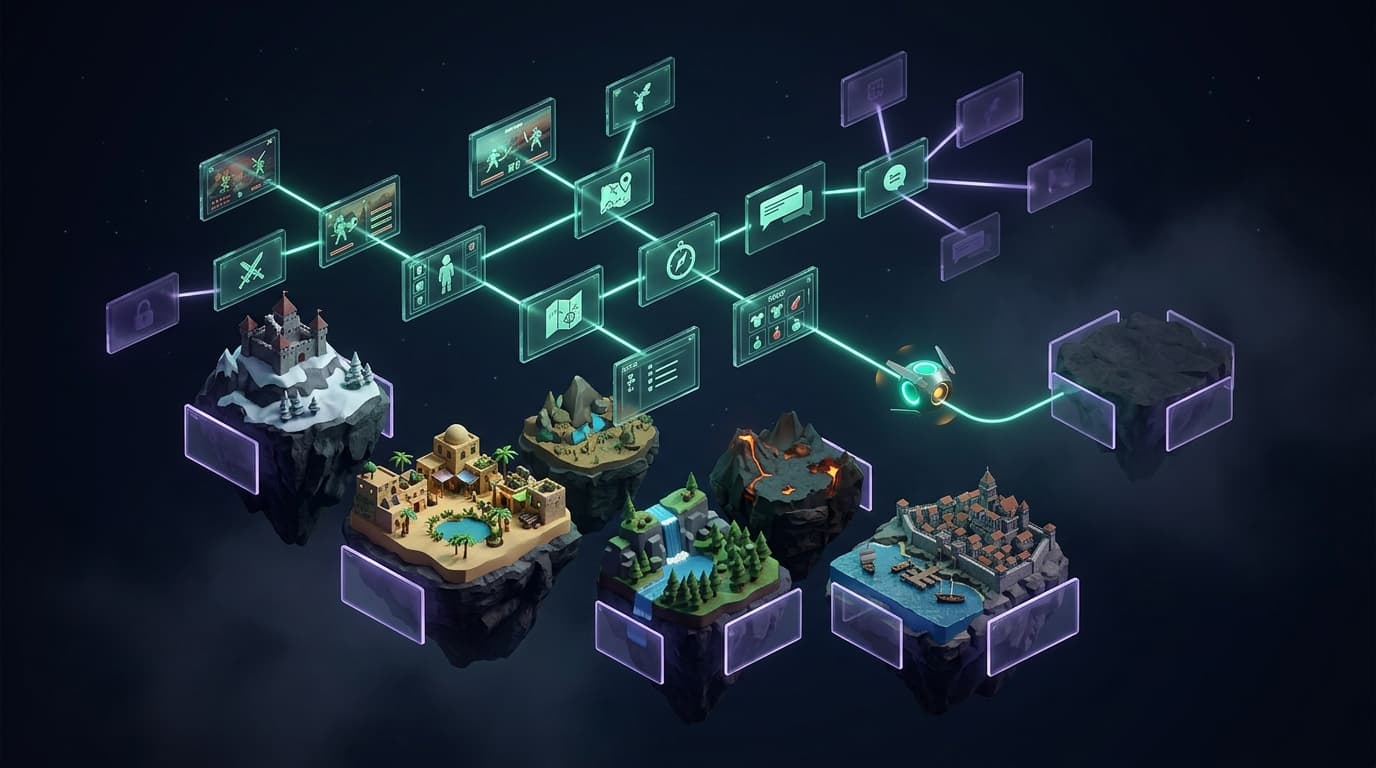
BugHunter builds that knowledge from four sources:
- Game documentation and test cases: mechanics, intended behavior, and the checks your team cares about.
- Gameplay and run data: observed paths, starting states, outcomes, and evidence.
- QA feedback: accepted or rejected findings, corrected expectations, and useful reproduction details.
- Build and issue history: what changed, what was fixed, and what needs checking again.
For the next worker, that knowledge is a head start: how to reach a feature, what's already been accepted, what needs re-checking after a change. The factory builds on what your team already knows instead of making every worker rediscover the same game from scratch.
That's the direction for Nodemori's workers beyond QA. BugHunter comes first because testing gives you a reason to learn the game — and an immediate use for that knowledge: checking the next build. Your team still decides what counts as accepted knowledge and what still needs a closer look.
A run that fails still teaches something about the game, and it still never counts as a pass. Recording what happened and accepting it as knowledge are separate steps.
Where BugHunter fits
BugHunter is the AI QA worker your team runs. Nodemori helps connect your game and set up the first checks; from there, your team picks builds, starts runs, reviews findings, and reuses approved checks on later builds. We're available for hands-on support whenever you need it.
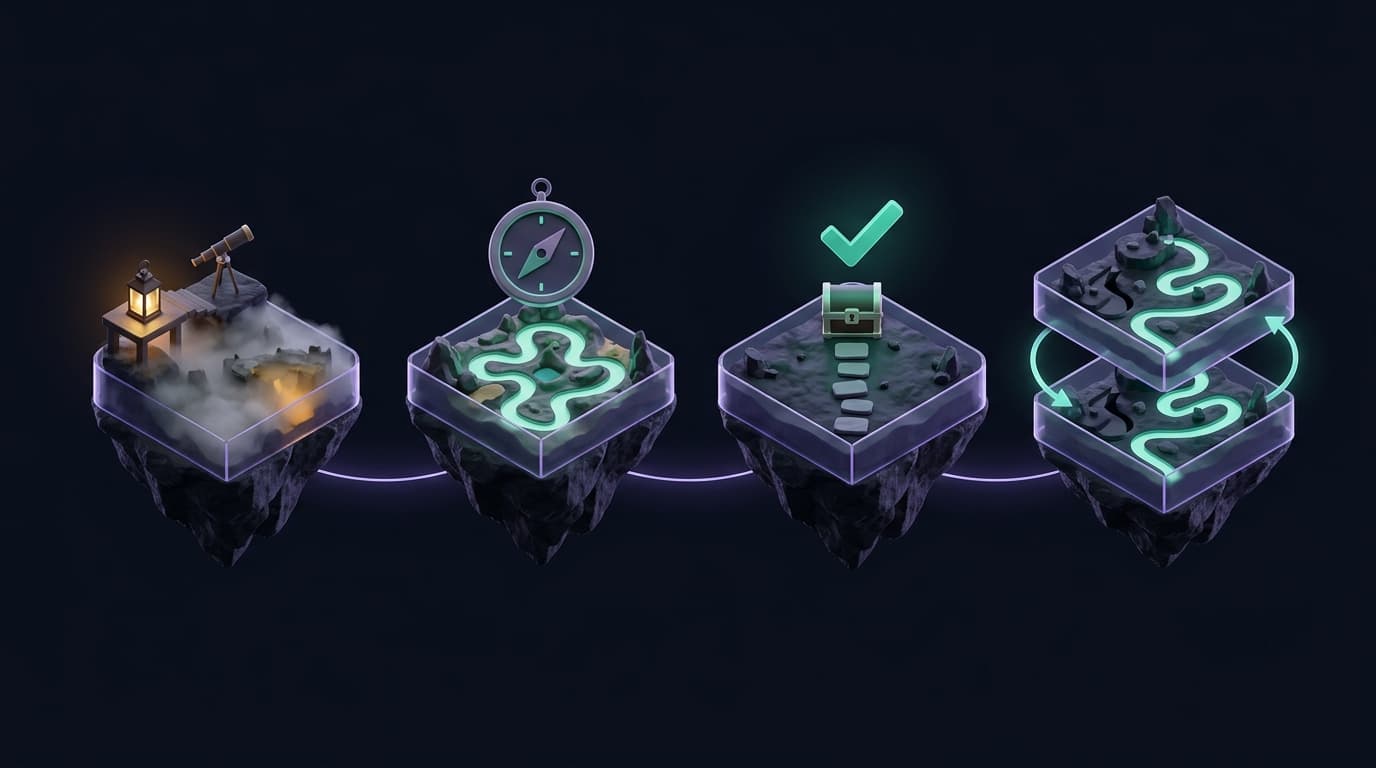
The work breaks into four tasks, and each one answers a different question:
- Freeplay explores toward an open-ended objective within a run limit. What happens when the worker goes after this goal?
- Testcase runs approved steps against an expectation. Does this check meet the expectation?
- Regression repeats accepted checks on a later build. Does the check still meet the expectation, and is the earlier issue fixed on this build?
- Scout looks at a selected area of the game and drafts candidate checks. What is here, and what is worth checking?
What's available depends on the game and the build.
For an AI Factory, repeatable Testcase and Regression work is the practical starting point. Exploration can surface a candidate issue; an accepted, repeatable check is what you actually reuse on the next build. That's how individual findings turn into a growing body of release evidence.
Running an AI QA worker doesn't automatically give you a release gate. You still decide which results can block a release, what the acceptance criteria are, and how an uncertain finding reaches a person.
Start with one loop the team can trust
Choose a recurring journey whose expected outcome is clear: tutorial completion, a saved progression state, or a reward claim. Establish the supported test environment and a known starting state. Then operate the whole sequence before expanding coverage.
- Agree the steps and the observable result with the person who owns the feature.
- Run the check on a known working build and inspect the evidence.
- In an isolated test build, deliberately break the target behavior and confirm that the check detects it.
- Repeat the check after the repair and preserve both outcomes.
- Define who handles a failure, an incomplete run, or an ambiguous result before using the check to control delivery.
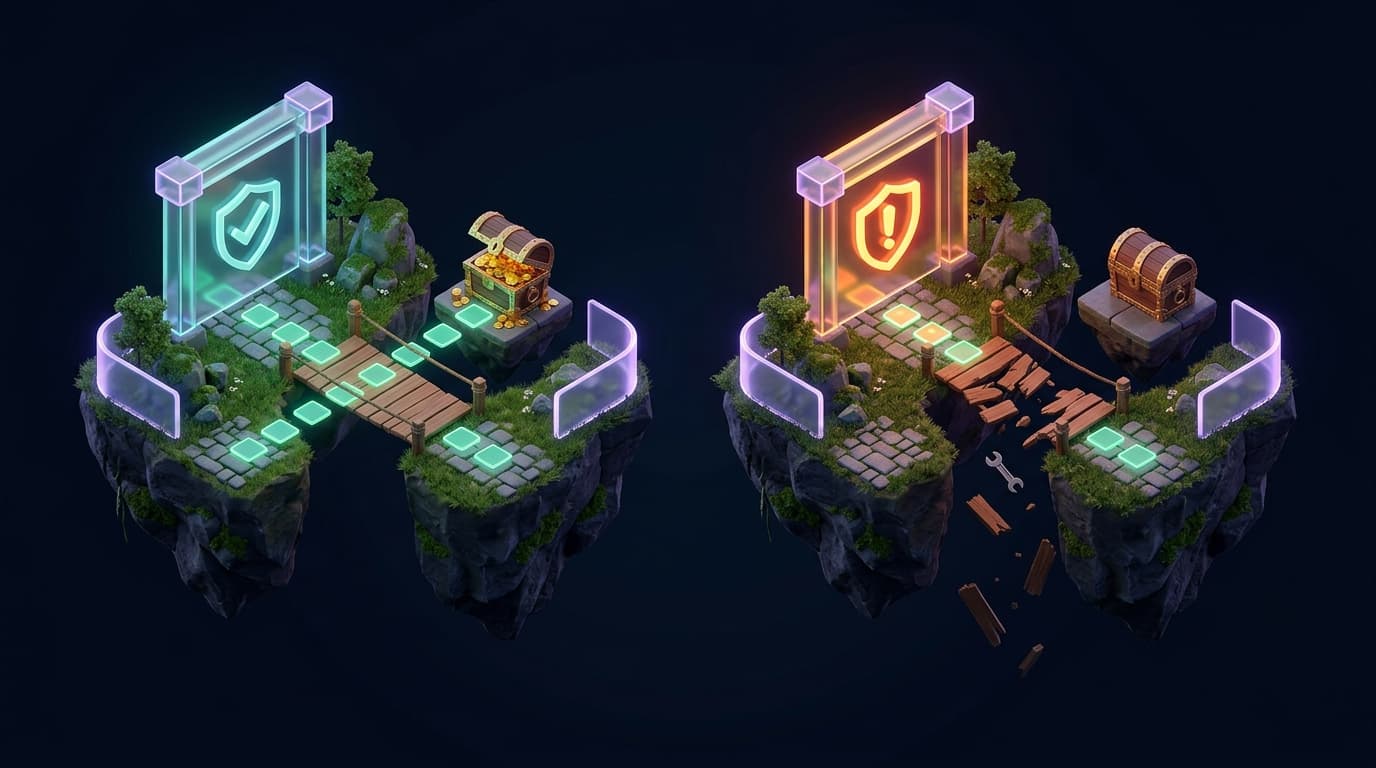
The deliberate break matters most. A check that stays green while the reward is switched off in a test build was never checking the reward.
For the reward journey, a first check can be this short. Starting state: a test account at the end of a level, with its coin balance recorded. Steps: finish the level, open the reward screen, and tap Claim. Expected result: the balance rises by the level reward exactly once, and the new balance is still there after a restart.
Keep creative judgment with the team
A repeatable check can tell you whether the reward was granted. It can't tell you whether the reward feels satisfying, whether the level is worth replaying, or whether the economy serves your design goals. Those calls need playtesting and product judgment — not a check.
What the factory should do is make that judgment better informed. AI QA brings repeatable execution into the delivery loop and hands your team observations to examine. You keep ownership of what quality means, and when the evidence is enough to ship.
See how BugHunter fits your workflow
Explore the product, the four QA tasks, and how your team stays in control.
Explore BugHunter